InfoQ Homepage Programming Content on InfoQ
-
From S3 to GPU in One Copy: Rethinking Data Loading for ML Training
Onur Satici discusses Vortex, an open-source columnar file format designed to bypass CPU bottlenecks, enabling ultra-fast S3-to-GPU data streaming and dynamic query pruning at up to 60 Gbps.
-
Beyond Prompting: Context Engineering for Production-Grade AI
Ricardo Ferreira explains how context engineering overcomes LLM latency, cost, and memory limitations in AI systems, sharing architectural lessons from building a custom Alexa backend with Redis.
-
Beyond Line Charts: Why Some Diversity in Telemetry Visualization Is Long Overdue
Yao Yue explains why line charts often fail during production incidents and shares how software architects & engineering leaders can transform telemetry data to answer critical operational questions.
-
Running AI at the Edge: Running Real Workloads Directly in the Browser
James Hall explains why engineering teams should shift AI workloads on-device. He shares local inference strategies, WebGPU optimization techniques, and architecture choices for zero-trust privacy.
-
Architecting the Data Layer for AI Agents: from Transactional Systems to MCP and Semantic Models
Fabiane Nardon explains how to architect enterprise data platforms for AI agents, balancing precision, security, and token costs using MCP, data mesh, and semantic web technologies.
-
Python, Numba, and Algorithm Design: Building Efficient Models in Financial Services
Chad Schuster explains how using Numba JIT compilation and GPUs speeds up compute-intensive Python models, driving 10x cloud cost reductions while navigating architecture trade-offs.
-
Can Claude Fix Itself? Using LLMs for Incident Response
Anthropic's Alex Palcuie shares how LLMs transform incident response, highlighting where Claude excels at log analysis and why automated AI SREs still can't replace human judgment.
-
Prompt to Prod: Engineering an Autonomous SDLC at Scale
Andrew Swerdlow shares how Roblox transitions from AI autocomplete to fully autonomous software development with "Prompt to Prod," covering safety guardrails, infrastructure, and metrics.
-
SafeChat: Building AI-Powered Safety Systems at Scale in a Real-Time Marketplace
Bruna Pereira shares how DoorDash built a scalable AI moderation platform. Learn how combining cheap classifiers with LLM scoring reduced incidents and cut latency in real-time chat.
-
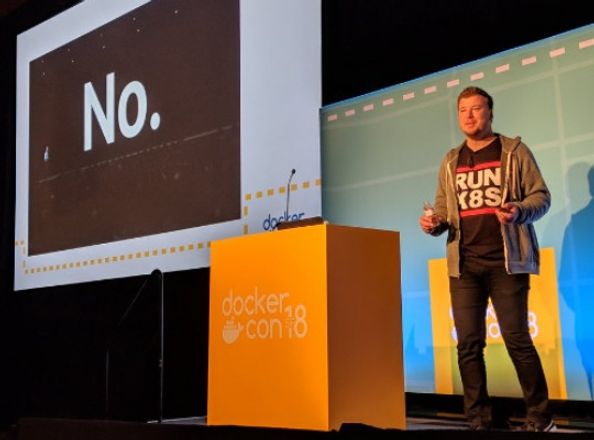
Enchant Your AI and APIs with eBPF Magic 🪄
Dan Finneran explains how to use eBPF and AI gateways in Kubernetes to transparently observe, modify, and control unowned AI agent API calls without altering source code.
-
From Fab To Token - The State Of The Market
Jordan Nanos explains how hardware constraints, data center scale, and chip co-design shape modern AI performance and tokenomics from silicon to inference.
-
From Thousands to One: Building LLM-Powered Selection Systems
Jendrik Jördening explains how to build reliable LLM architecture by enforcing strict schemas, separating AI text reasoning from deterministic code, and applying automated output validation.